Dense supervision wins on every dataset
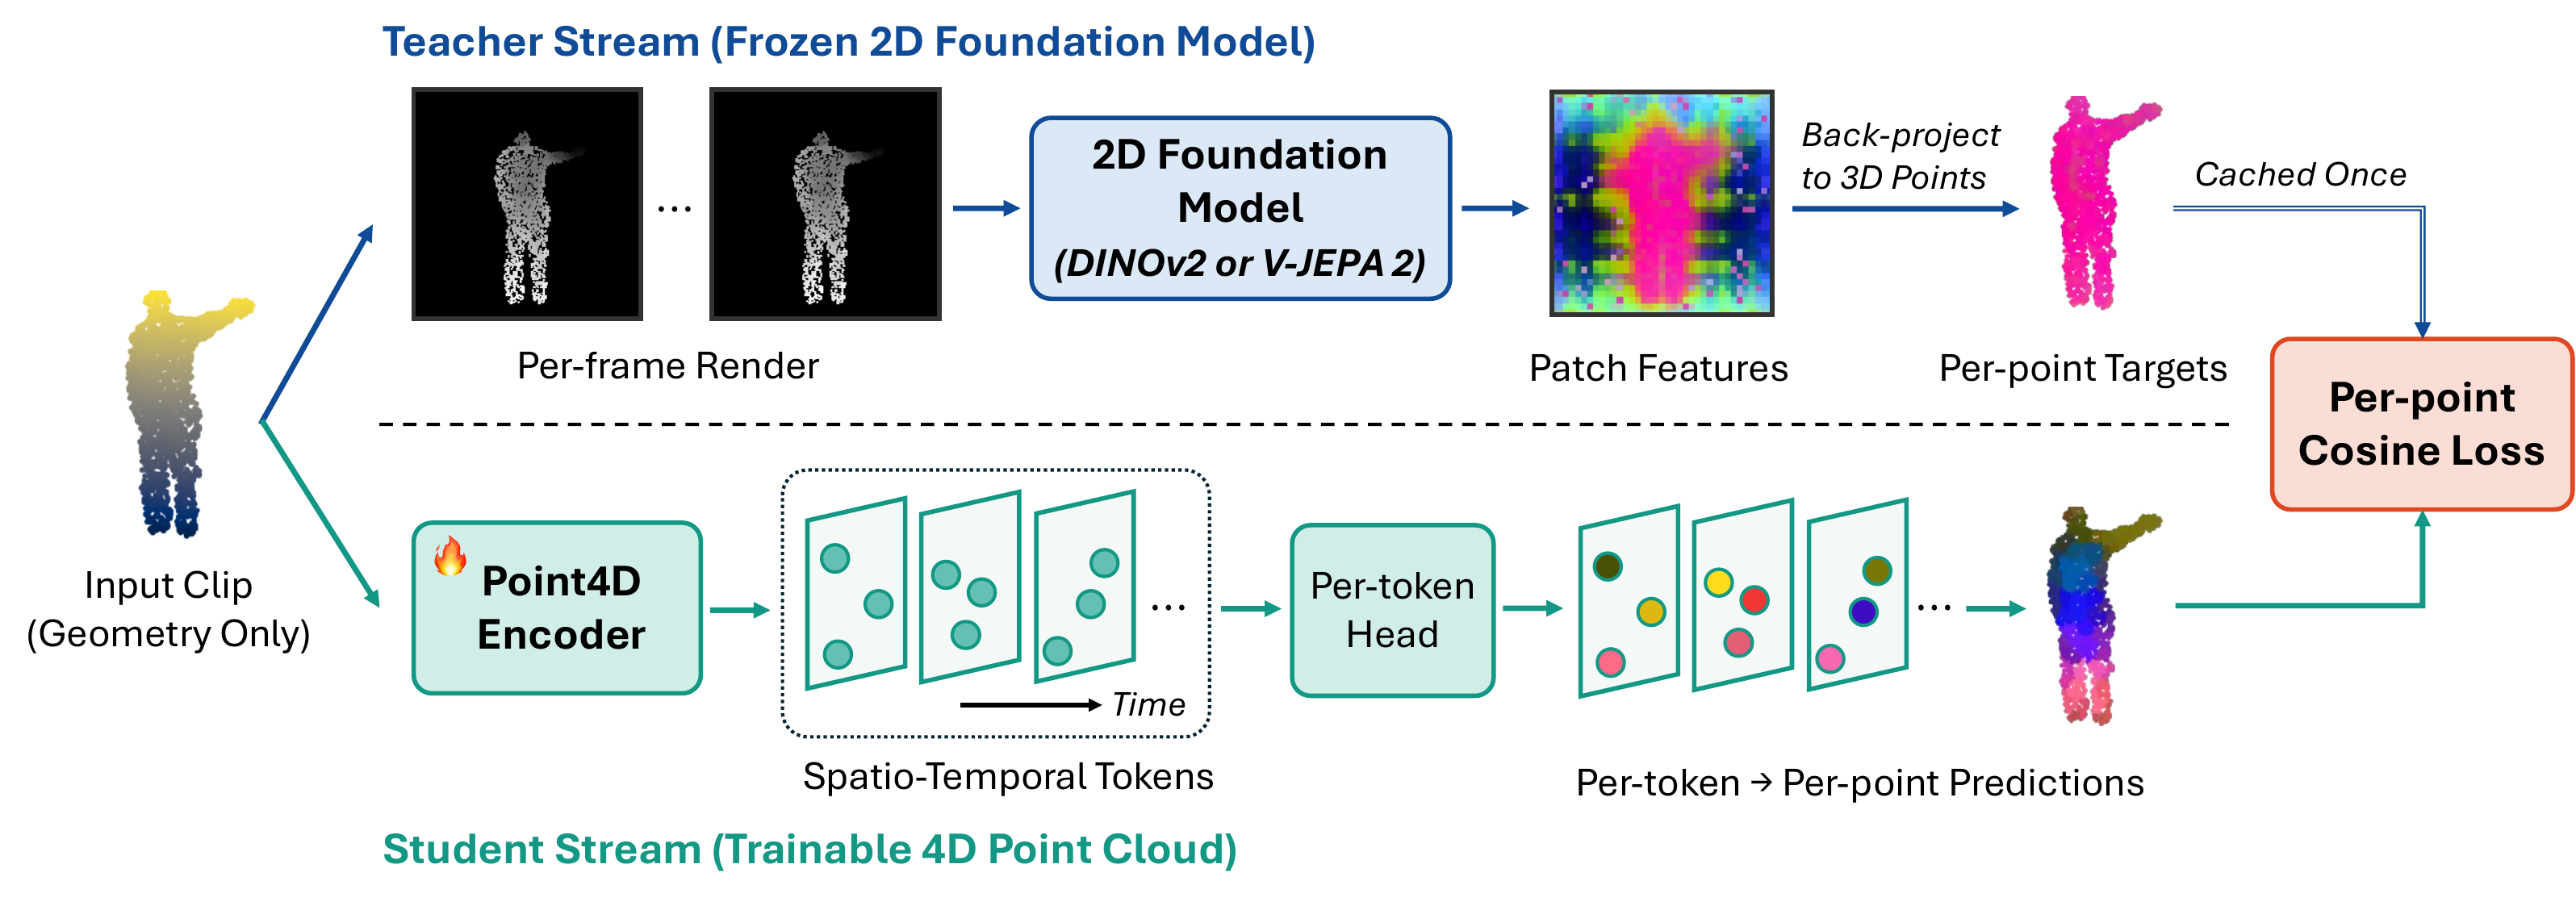
With the same teacher, student and budget, predicting per-point targets beats predicting one global target per clip by 0.18 to 0.29, several times either error bar.
Table 1. MSR-Action3D uses DINOv2 (5 dense / 8 global seeds); DeformingThings4D and NTU RGB+D 60 use V-JEPA 2 (5 seeds each).